DX-M1 AI Accelerator M.2 Module with 4GB LPDDR5 (25 TOPS)
9.900,00 EGP
The DX-M1 AI Accelerator M.2 Module delivers server-class edge computing power, packing 25 TOPS (INT8) of inference performance into a standard M.2 2280 form factor with ultra-low power consumption (2W–5W). Equipped with 4GB LPDDR5 memory and a PCIe Gen3 x4 interface, this NPU ensures low-latency processing and seamless compatibility with Raspberry Pi 5, LattePanda, and various x86/ARM platforms. Supported by the comprehensive DXNN® SDK for PyTorch, ONNX, and TensorFlow, it is the ideal solution for deploying complex AI models in intelligent robotics, visual SLAM, and industrial automation systems.

Figure: DX-M1 AI Accelerator M.2 Module Functional Block Diagram
Server-Class Inference at the Edge
The core strength of this M.2 AI module lies in the ability to deliver 25 TOPS of INT8 performance, a figure previously reserved for power-hungry server components. This massive computational headroom allows for the execution of complex neural networks and multi-stream video analysis directly on the edge device without relying on cloud connectivity. Despite this high performance, the advanced architecture ensures energy efficiency, operating within a strictly controlled 2W-5W power envelope, significantly reducing heat generation and extending operation time in mobile robotic platforms.
Universal M.2 Compatibility & Integration
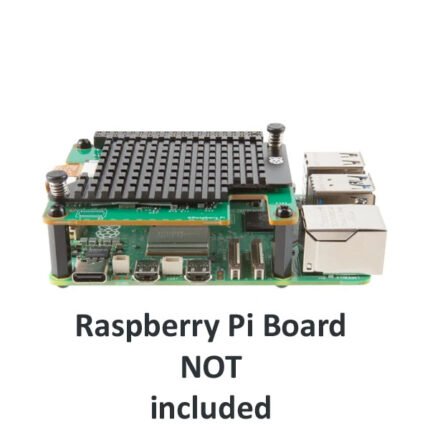
Designed with the industry-standard M.2 M-Key (2280) interface, the accelerator card ensures broad interoperability across various computing platforms. It utilizes the PCIe Gen3 x4 protocol (backward compatible with x1 mode) to maximize data throughput. This standardization allows system integrators and developers to easily upgrade existing x86 PCs, LattePanda single-board computers, or Raspberry Pi 5 setups (via HATs), instantly adding extensive AI capabilities to standard hardware infrastructure.
Seamless Development Toolchain
The hardware is backed by the robust DXNN® SDK, which streamlines the transition from model training to edge deployment. The toolchain provides a complete environment for compilation, optimization, and runtime execution, removing the traditional barriers associated with NPU development. Popular deep learning frameworks including PyTorch, TensorFlow, TensorFlow Lite, Keras, and XGBoost are natively supported, allowing algorithms to be ported via ONNX format with minimal friction.
Industrial-Grade Reliability
Beyond raw performance, the DX-M1 is built to withstand rigorous operating environments. The module features 4GB of onboard LPDDR5 memory to handle large models and heavy batch processing efficiently, alongside 1Tbit of QSPI NAND Flash for firmware stability. With an operational temperature range spanning from -25°C to 85°C, the device is qualified for industrial automation, outdoor security monitoring, and other harsh application scenarios where consumer-grade electronics typically fail.
Video: Butter Benchmark: AI Chip Battle – 94% Energy Cost Savings Proven!
Applications
- Robotics: Visual SLAM & Navigation
- Edge Computing: Real-time Video Analytics & Object Detection
- Industrial: AI Visual Inspection & Safety Monitoring
- Autonomous Systems: Drone Perception & Self-Driving Platforms
Specification
- Processor Performance: 25 TOPS (INT8)
- Interface: M.2 M-Key, PCI Express Gen3 x4 (compatible with x1 mode)
- Memory: 4GB LPDDR5, 1Tbit QSPI NAND Flash
- Power Consumption: 2W ~ 5W
- Power Range: 3.3V±5%
- Framework Support: PyTorch, ONNX, TensorFlow, TensorFlow Lite, Keras, XGBoost
- Operating Systems: Windows 10/11, Ubuntu 20.04/22.04 LTS
- Operating Temperature: -25°C ~ 85°C (Throttling); 25°C ~ 65°C (Non_ Throttling)
- Product Dimensions: 22 mm x 80 mm x 4.1 mm/0.87 inch x 3.15 inch x 0.16 inch
Shipping List
- DX-M1 AI Accelerator M.2 Module with 4GB LPDDR5 x1

Reviews
There are no reviews yet.